
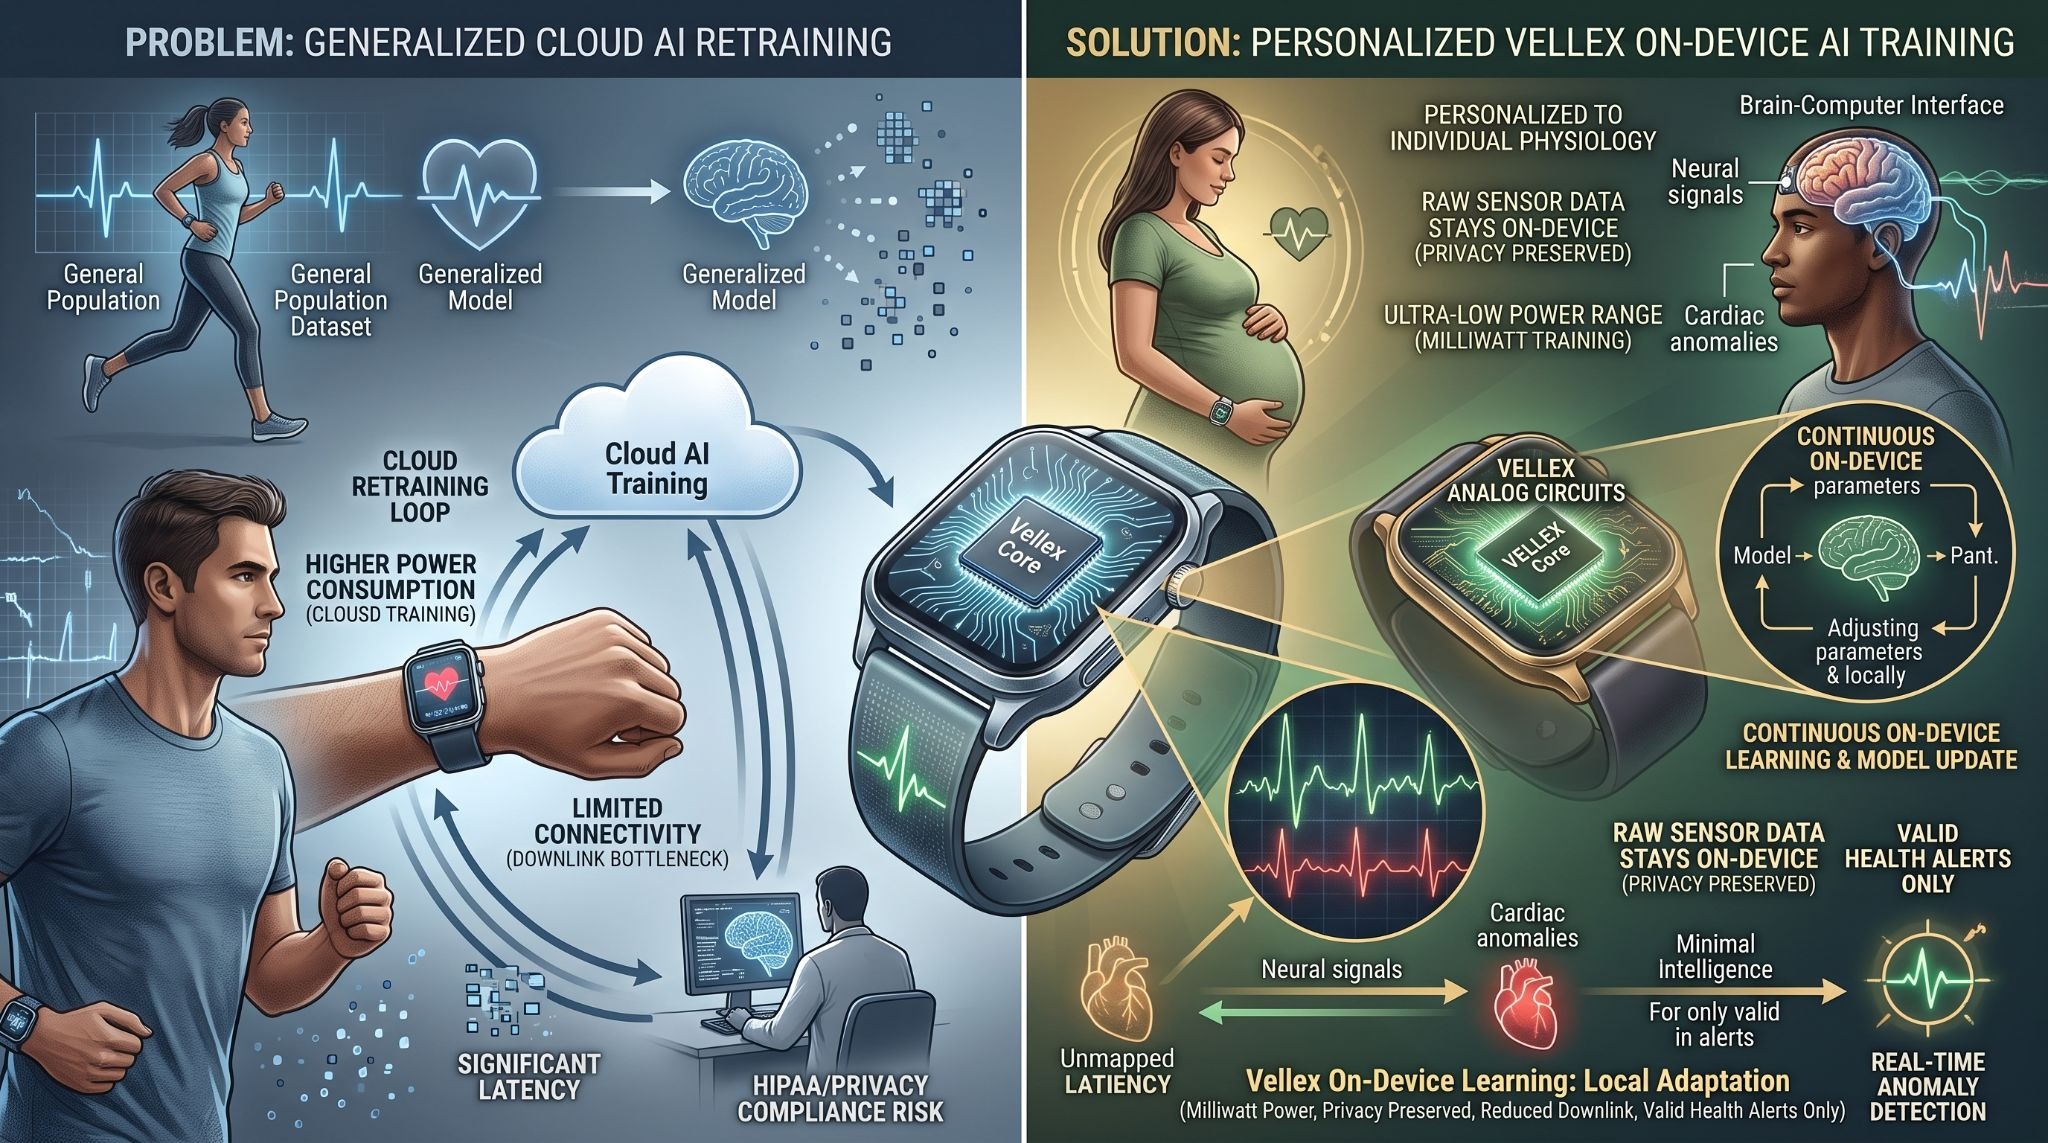
Human biology is highly variable, and static models degrade as a result. Every wearer's physiology is different: baseline heart rates, neural patterns, and metabolic markers vary significantly across individuals. A model trained on a broad population dataset loses accuracy when applied to a specific wearer. This is model drift. Restoring accuracy requires updating the model's parameters to match the individual, and current hardware forces that process off-device.
The standard approach is a cloud retraining loop. The wearable transmits raw biometric data to a remote server, the model is retrained in a data center, and the updated parameters are pushed back to the device.
Transmitting raw biosignals off-device conflicts directly with frameworks like HIPAA and creates real data exposure risk. Continuous health monitors generate high volumes of sensitive personal data. Routing that data through cloud infrastructure for routine model updates turns a standard engineering decision into a compliance and security liability.
Latency compounds this. For a continuous monitor detecting acute anomalies, waiting hours for a remote retraining cycle is not a viable update cadence.
The alternative is to run training directly on the wearable, which would eliminate the data transmission requirement. The barrier is power.
Standard digital processors run AI training through continuous data movement between memory and compute cores, calculating gradients over millions of clock cycles. This draws watts of power. Wearables operate on milliwatt battery budgets. Allocating that budget to a digital training workload drains the battery rapidly and disrupts continuous monitoring. This power gap is what keeps training off the device.
A system capable of training locally keeps raw biosignals on the device. It uses whatever connectivity it has only for critical health alerts, not for data uploads. Models adapt to the wearer's physiological baselines continuously, without transmitting personal data off-device.
The cost of cloud retraining is not primarily the infrastructure overhead. It is the operational dependency it creates: every biometric system that relies on data center retraining inherits the latency, data pipeline requirements, and compliance risk of that architecture.
Vellex builds analog compute hardware that runs AI training directly on-device. The approach maps optimization mathematics onto analog circuits, which settle to a solution through circuit dynamics rather than iterating through discrete digital steps. The result is AI training at power levels compatible with the battery constraints of wearable medical devices.
Systems built on Vellex hardware personalize to the wearer autonomously, maintaining model accuracy without transmitting sensitive biometric data off-device or allocating battery capacity to a digital training workload.
READ MORE


